🏋️ 预训练:先把图书馆读一遍🏋️ Pre-Training: Read the Library First
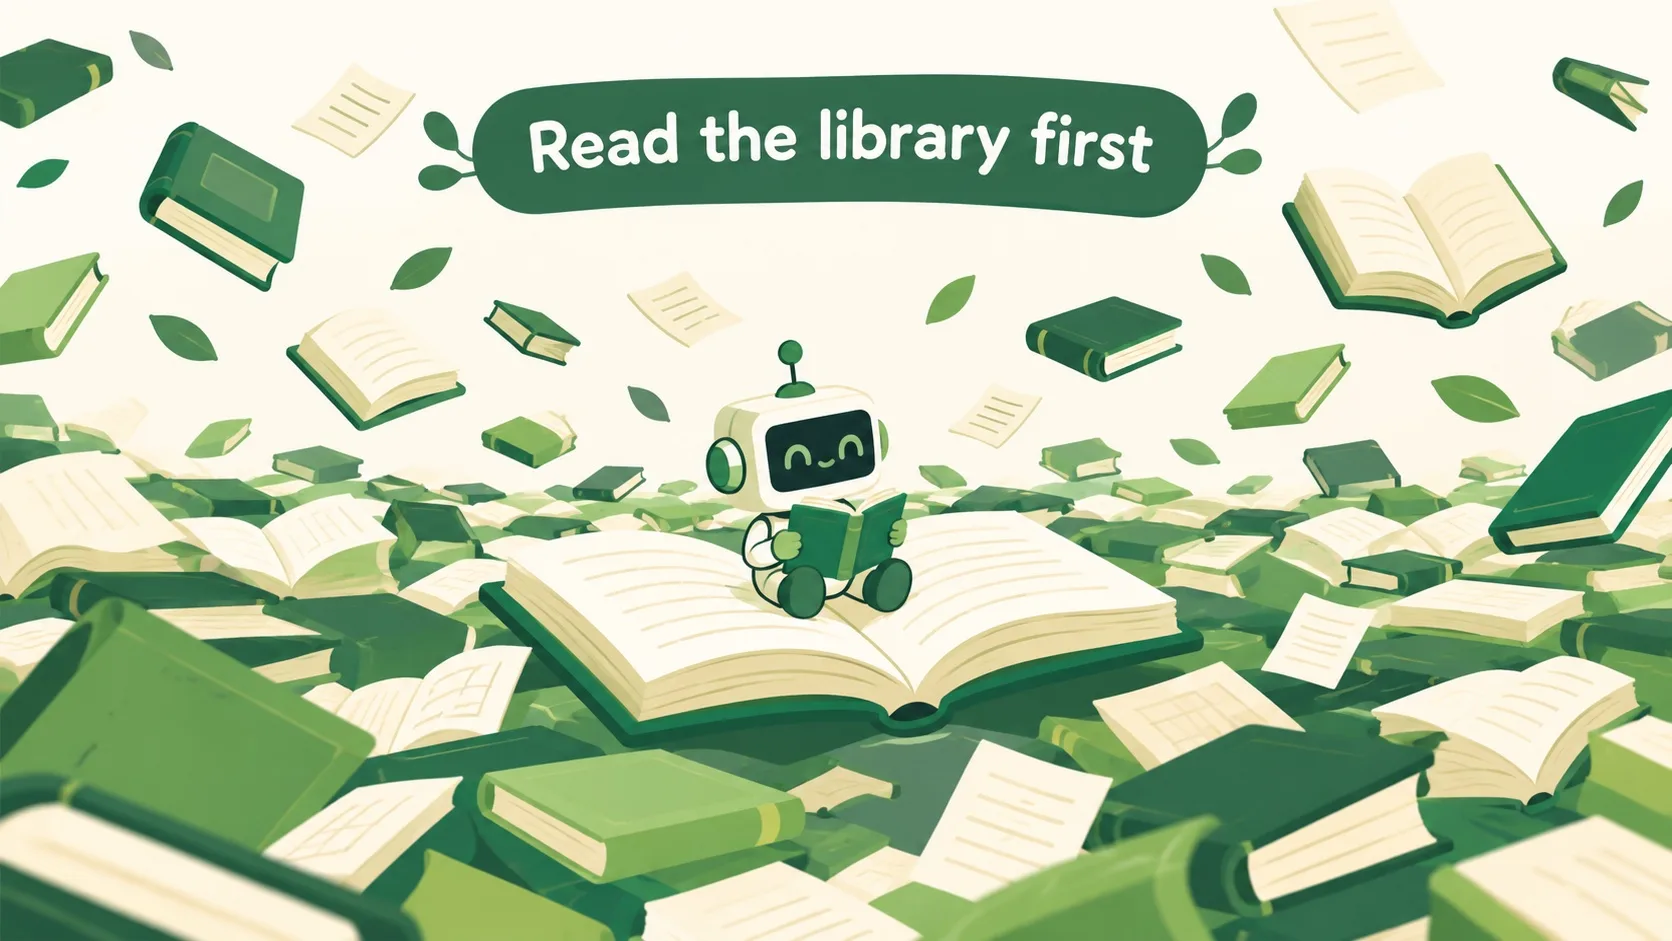
上一片里,文字被切成了一颗颗词元。可词元自己不会变成本事——上岗之前,模型要先干一件大事:把互联网“读”一遍。这就是预训练。Last leaf, text was sliced into tokens. But tokens alone teach nothing — before the model can go to work, it first has to “read” the internet from cover to cover. That is pre-training.
第 1 步:先读一万本,再上岗Step 1: Read the library first
没有老师出题,它到底从书里学什么?With no teacher setting homework, what does it actually learn from all that reading?
上岗前,模型先泡进几万亿词元的文本:网页、书籍、代码,什么都读。它不背答案,只学两件事——语言怎么组织,世界长什么样。读得越多,底子越厚;这层通用底子,就是预训练。Before its first day, the model soaks in trillions of tokens of text — web pages, books, code, everything. It doesn’t memorise answers; it quietly picks up two things: how language fits together, and what the world is like. The more it reads, the thicker its foundation — that general foundation is pre-training.
可是没人批改作业,练习册又是从哪儿来的?But with no one grading its homework — where do the exercises come from?
第 2 步:两招自学:遮词和接龙Step 2: Two self-taught drills
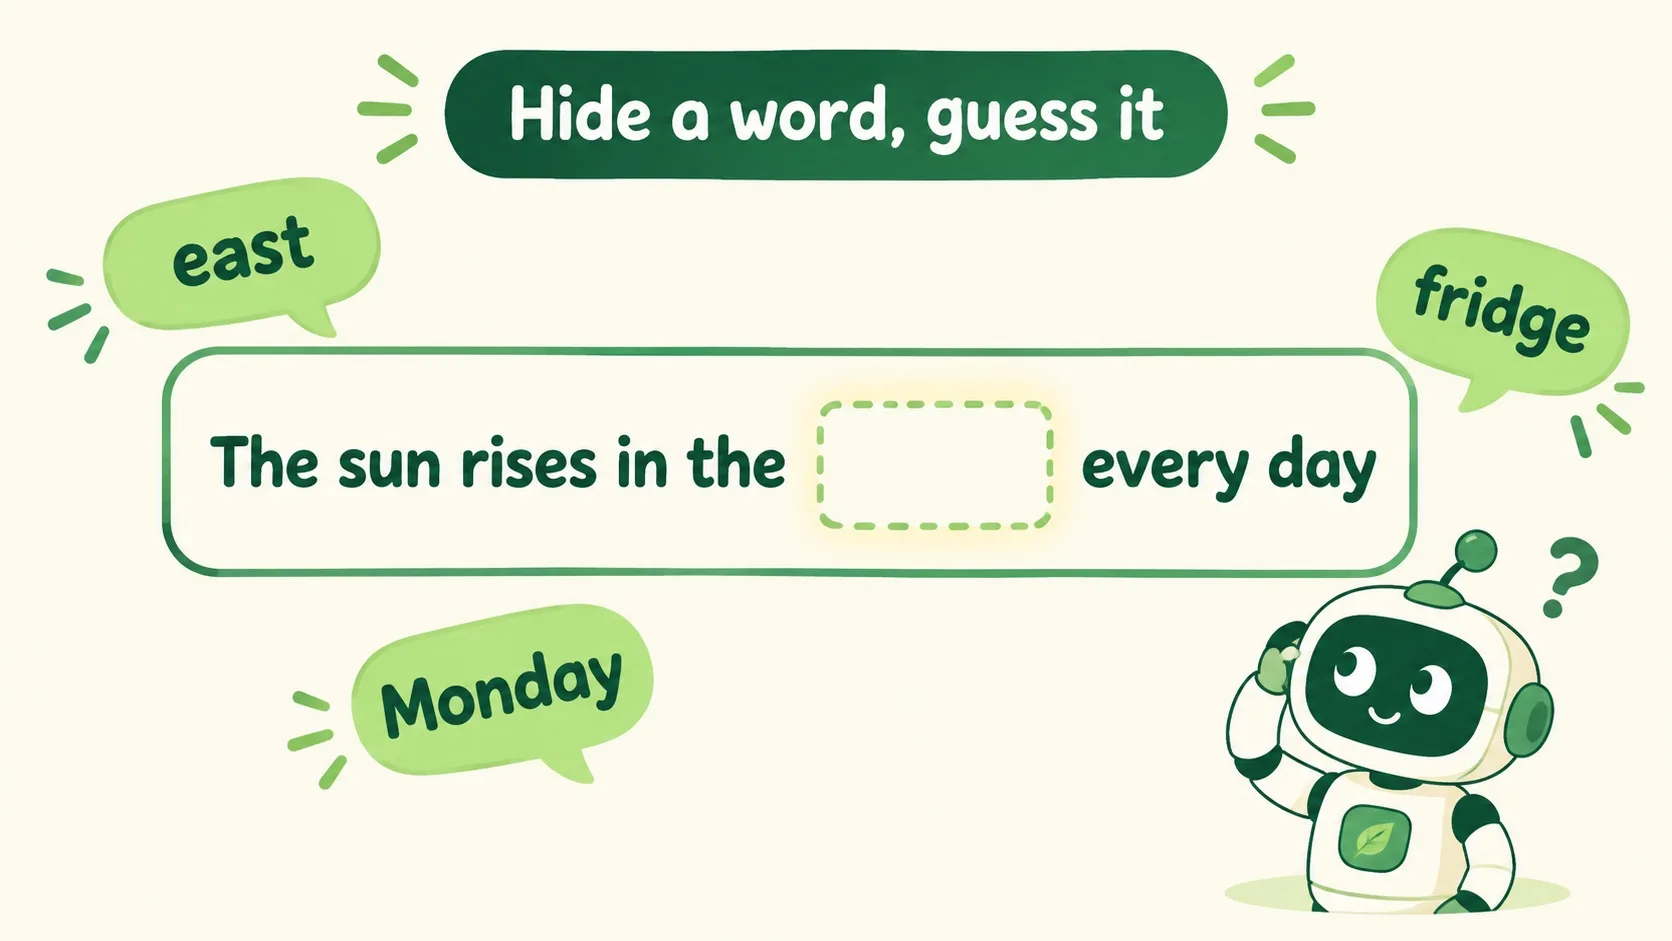
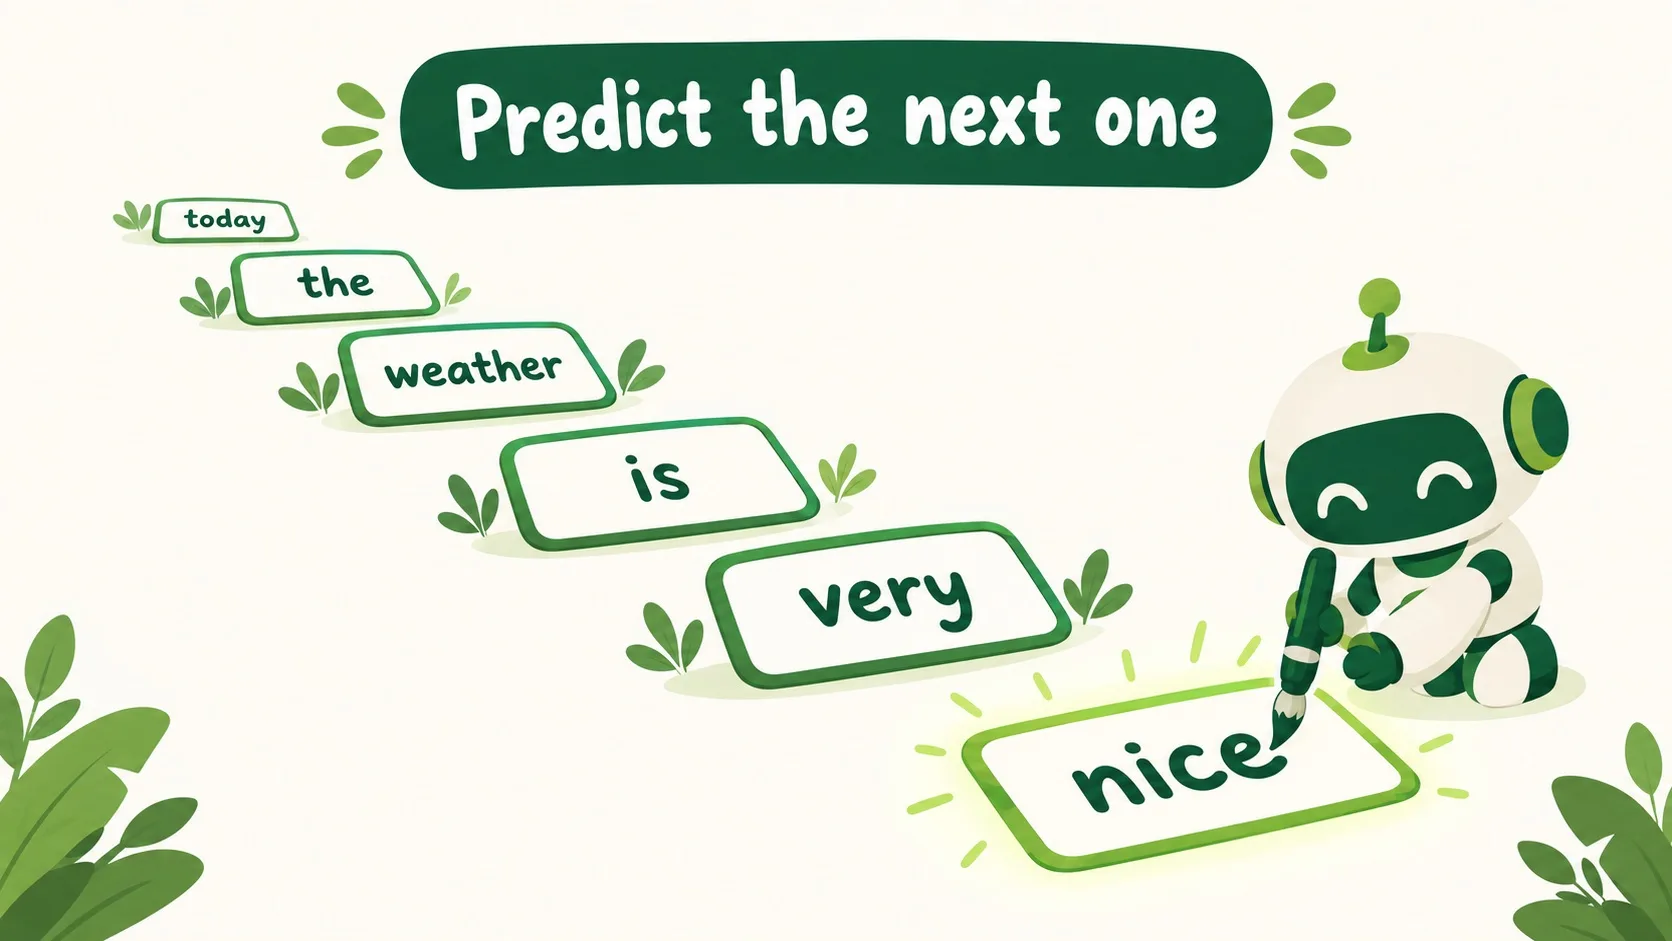
答案就藏在句子里。第一招:遮住一个词,让它猜(完形填空);第二招:看前文,猜下一个词(接龙)。每一句话都自带标准答案,不用人工标注。模型就这样自己出题自己练,一遍又一遍。The answer key hides inside every sentence. Drill one: cover one word and let it guess (fill-in-the-blank). Drill two: read the start, predict the next word. Each sentence grades itself — no human labelling needed. The model sets its own exercises and repeats them, again and again.
读了这么多、练了这么久,最后得到什么?After all that reading and drilling, what comes out?
第 3 步:产出:一个“什么都懂一点”的基座模型Step 3: Out comes a base model
它练成了一个基座模型:会说话、懂常识、什么都懂一点。但它还不太听指令——你说“帮我总结”,它可能只顾接着往下续写。学会听话,是下一片微调的事。Out comes a base model: it can talk, it knows common sense, and it knows a little about everything. But it still doesn’t take orders well — ask it to “summarise”, and it may just keep writing. Learning to obey is the next leaf’s job: fine-tuning.
🎮 你来当一回预训练(30 秒)🎮 Your turn: pre-train yourself (30 seconds)
道理讲完了。下面 4 句话各遮住一个词——像模型一样,从上下文里把它猜出来。Theory done. Four sentences below each hide one word — guess it from context, just like the model does.
一句话记住它:预训练 = 上岗前先把互联网读一遍;靠遮词和接龙自学,攒出一个什么都懂一点的基座模型——听不听指令,是微调的事。Remember it in one line: pre-training is reading the internet before the first day of work — self-taught through hidden-word and next-word drills, producing a base model that knows a bit of everything. Following instructions comes later, with fine-tuning.
读几万亿词元:学的是语言规律和世界常识,不是背答案Trillions of tokens: it learns language patterns and world common sense — not memorised answers两招自学:完形填空(遮词猜词)和接龙(猜下一个词),不用人工标注Two self-taught drills: fill-in-the-blank and next-word prediction, no human labels needed产出基座模型:会说话、懂常识,但还不太听指令——那是微调的事Output: a base model that talks and knows a bit of everything — still needs fine-tuning to follow orders
内容参考 OpenStax 等公开教材,多来源核对 · AI 生成、人工审核 · 发现错误欢迎指正,帮这片叶子长得更好。Based on OpenStax and other open textbooks, cross-checked across sources · AI-generated, human-reviewed · Spotted a mistake? Tell us — help this leaf grow.
 Back to tree