上一片里,机器人把糖盐题背得滚瓜烂熟,一考新题却全错——那是过拟合。这一片请出一根“罚金绳”,专门拉住想撒欢的它。Last leaf, the robot memorised every sugar-or-salt question — then flunked a fresh set. That's overfitting. This leaf brings out the “penalty rope” that holds a runaway robot back.
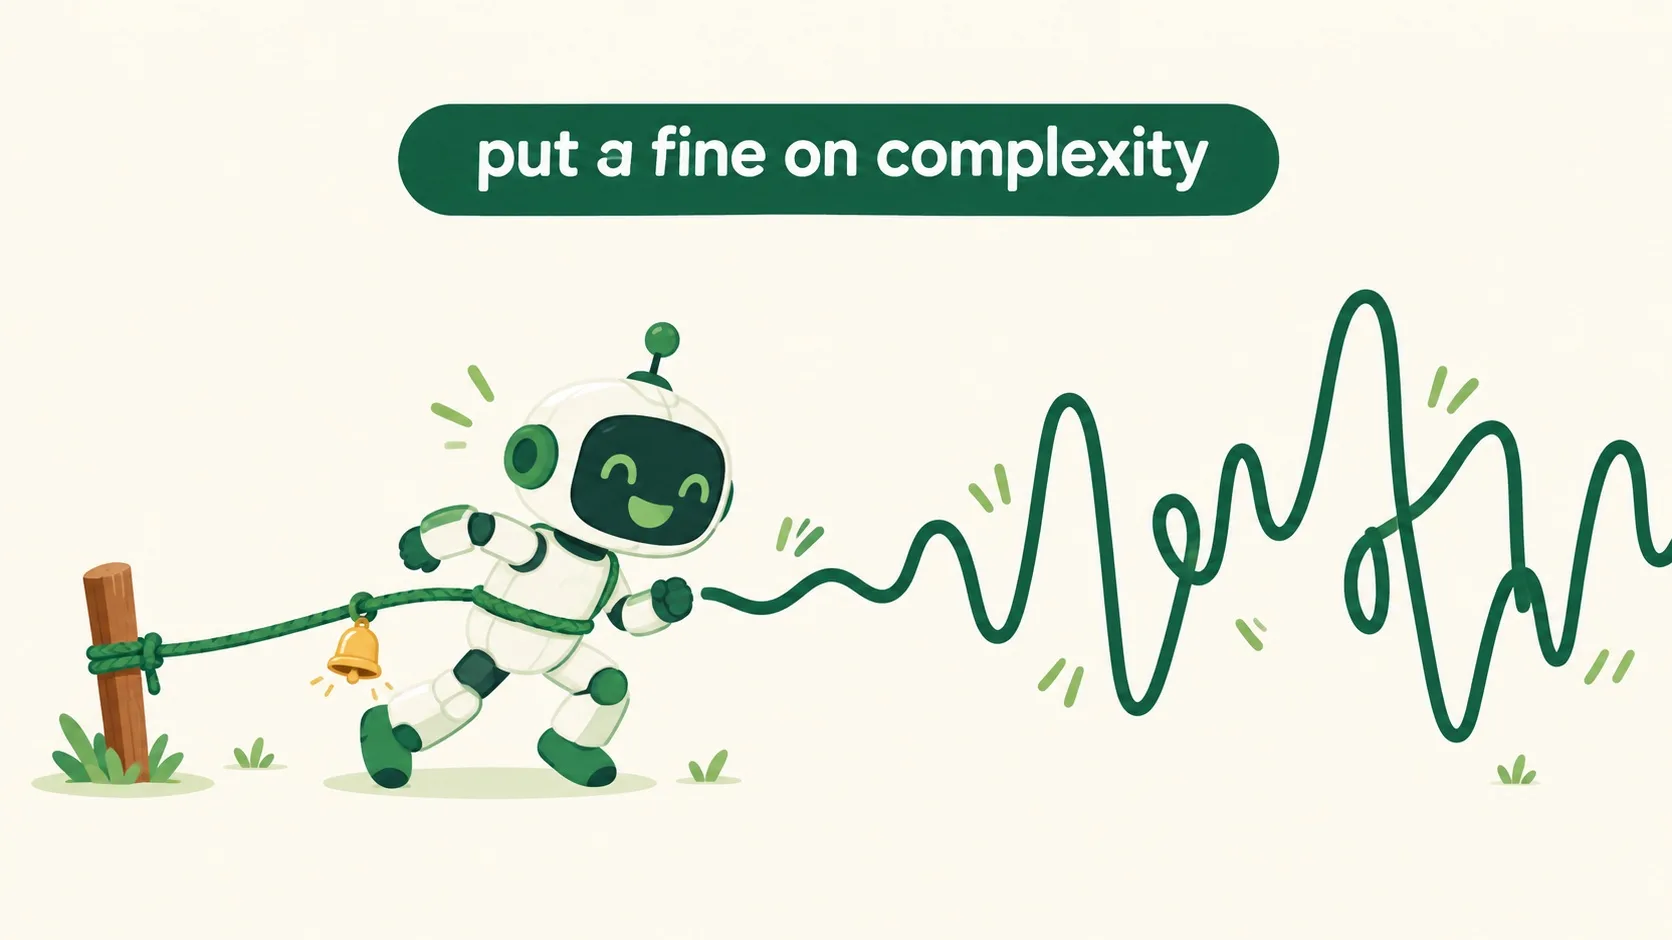
第 1 步:给复杂加罚金Step 1: Put a fine on complexity
怎么拦住一个背题狂魔?不用骂它——给它加一笔“罚金”。How do you stop a memorising maniac? Don't scold it — charge it a fine.
给模型算账时多加一笔:总账 = 答错的损失 + λ × 复杂度。λ 读作“拉姆达”,就是罚金力度。曲线每多一个弯、参数每多一份,罚金就跳高一格。越复杂罚得越狠——想撒欢背题的机器人,被这根罚金绳轻轻拴住了。Add one more item to the robot's bill: total = loss from wrong answers + λ × complexity. λ is the fine rate. Every extra wiggle in the curve, every extra parameter, pushes the fine one notch higher: the more complex, the harder the fine. The memorising robot gets gently held back by this penalty rope.
罚金定多重才合适呢?But how heavy should the fine be?
第 2 步:罚金旋钮Step 2: The penalty knob
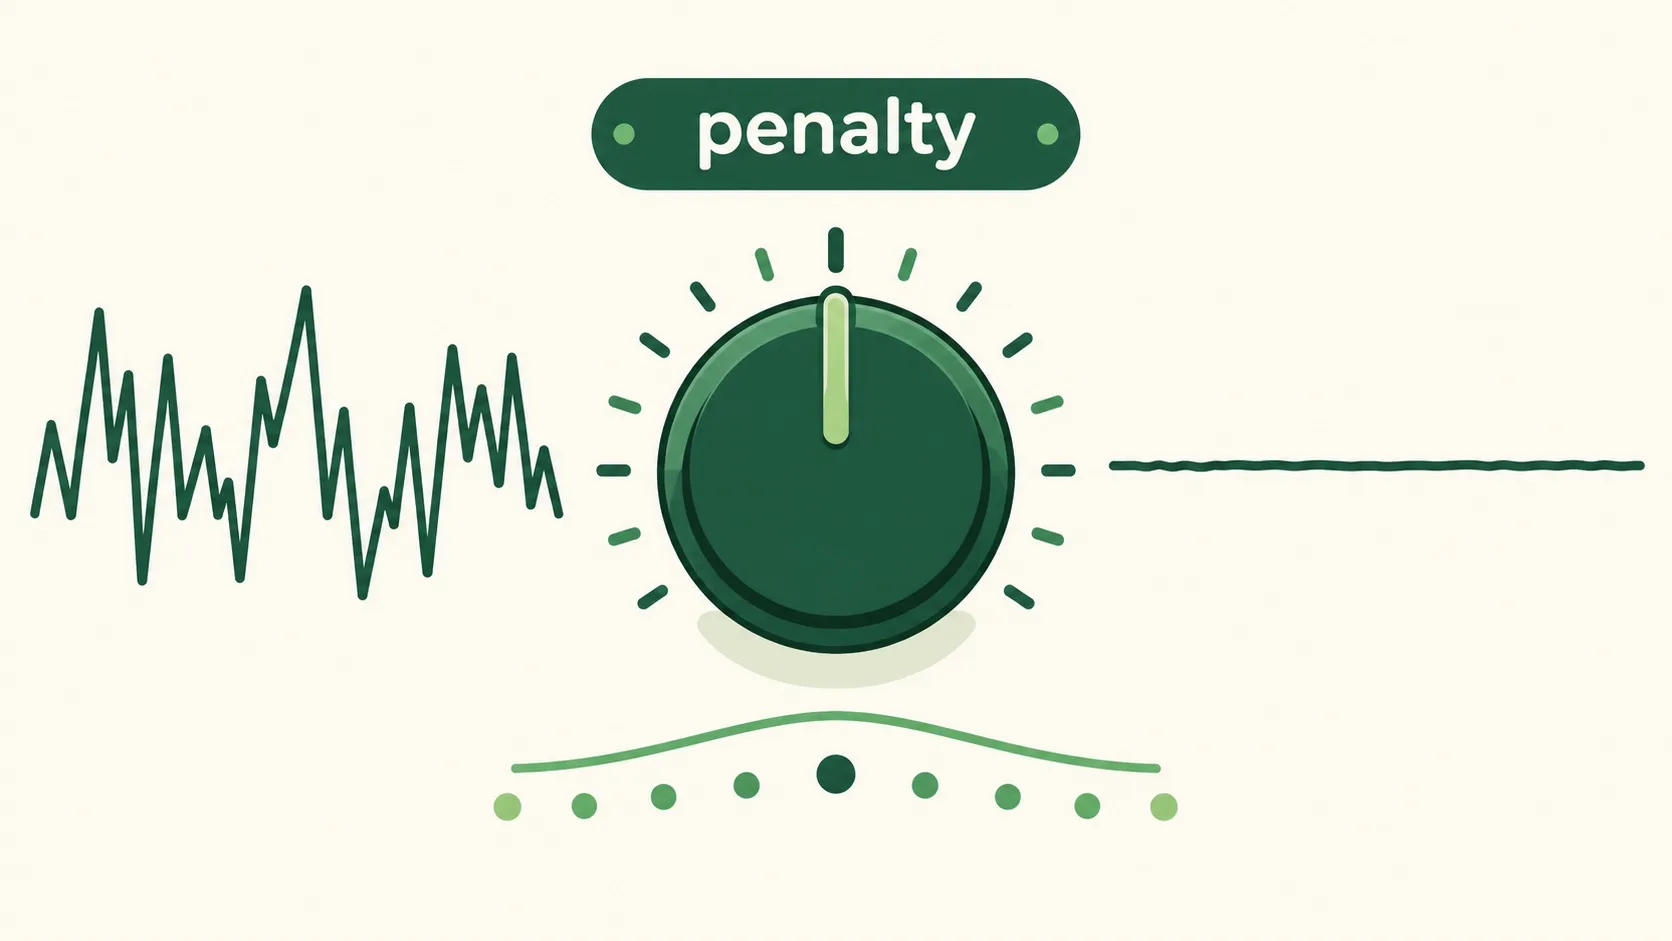
不背公式,拧一根旋钮就好:旋钮 λ 管着罚金力度,工程里也常叫它“权重衰减”(weight decay)——同一根旋钮的另一个名字。三档差别很大:太松,罚金形同虚设,机器人照样撒欢背题,画出歪歪扭扭的乱线;太紧,罚到它不敢学任何细节,只剩一块平板;拧到中间,曲线平滑又贴合,考新题也稳。旋钮不大,位置决定成败。No formula needed — just turn one knob. The knob λ sets the fine; engineers also call the same idea “weight decay”. Three zones, very different: too loose — the fine is an empty threat, the robot memorises on, drawing a wild wiggly line; too tight — it's scared into learning nothing, leaving a flat plank; in the middle — smooth, fitting, and steady on new questions. A small knob decides everything.
听起来不错,可是到底强多少?Sounds good — but how much better is it, really?
第 3 步:两根柱子见真章Step 3: Two bars tell the truth
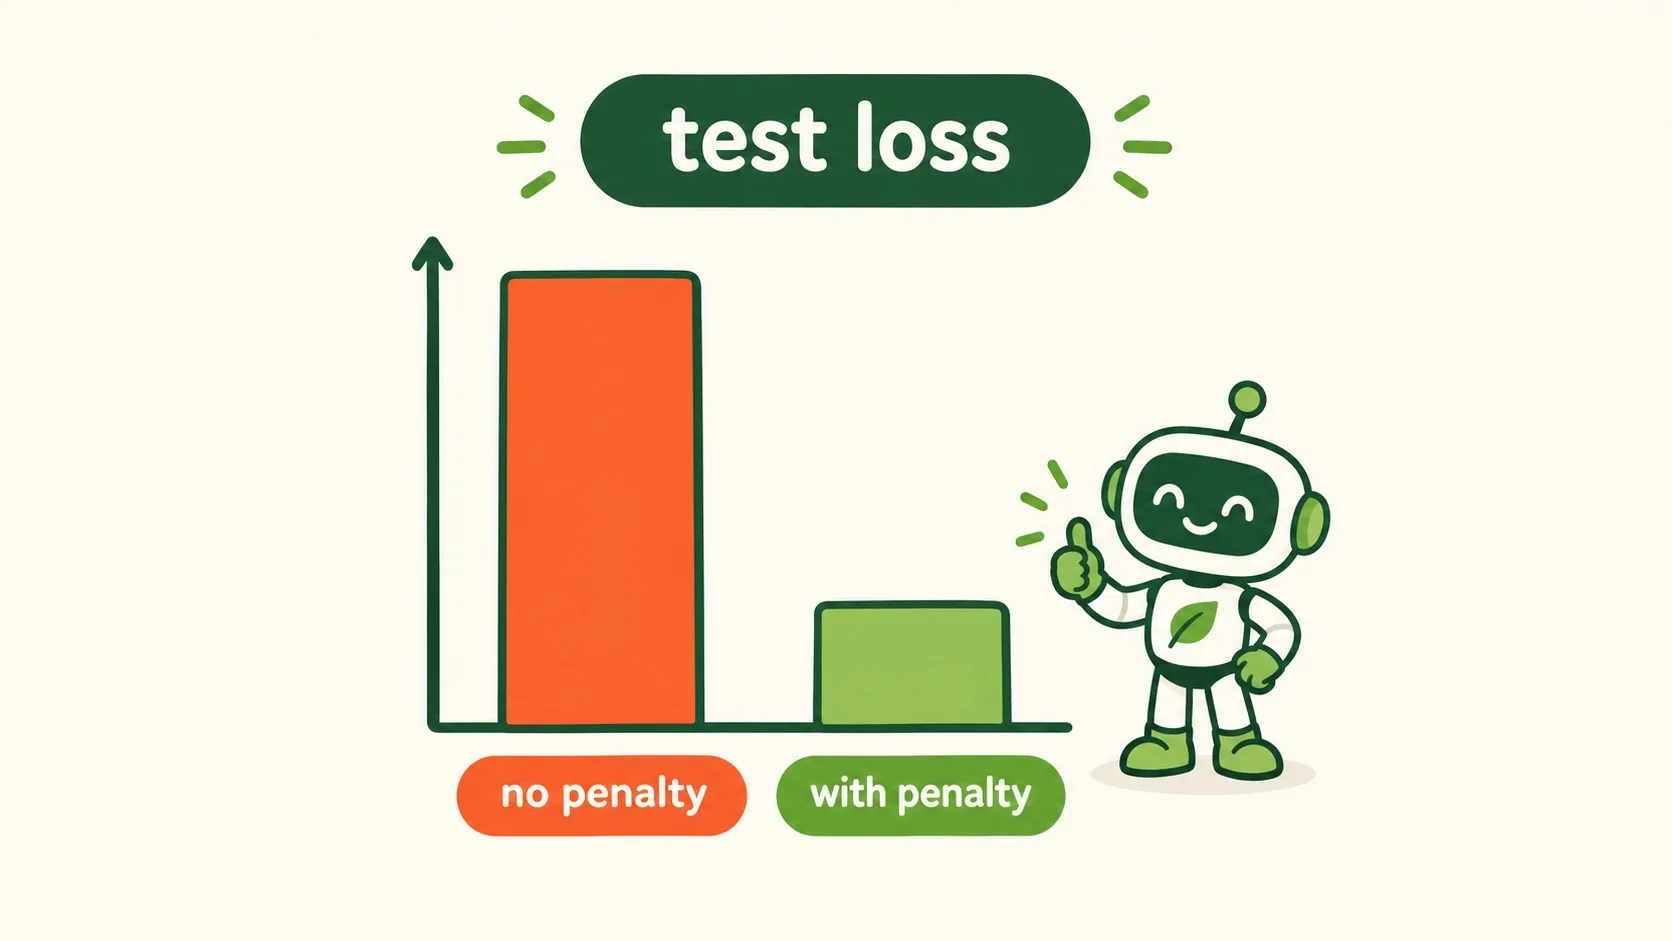
同一批题、同一个网络:不加罚金,训练分几乎满分,测试误差却高得离谱——一考新题就露馅;加了罚金,训练分略降一点(背下的东西少了),测试误差明显更低。这点“训练上的小小让步”,换来的是考场上的稳稳发挥——值。Same questions, same network: with no penalty, near-perfect training scores but a huge test loss — fresh questions expose it. With the penalty, training scores dip a little (fewer things memorised) while test loss drops a lot. A small concession in training buys steady performance in the exam — worth it.
🎮 你来拧罚金旋钮(30 秒)🎮 Your turn: turn the penalty knob (30 seconds)
拖旋钮,看拟合曲线从乱线变平板、测试误差先降后升——把误差压到最低的区间,就通关。Drag the knob: watch the fitting line go wild, then flat, as the test loss dips then rises. Push the loss into its lowest zone to win.
一句话记住它:正则化 = 给复杂加罚金;用一根 λ 旋钮,把爱背题的模型拉回“又准又稳”。Remember it in one line: regularization = a fine on complexity; one λ knob pulls a memorising model back to accurate-and-calm.
总账 = 答错的损失 + λ × 复杂度:越复杂,罚得越狠Total = loss + λ × complexity: the more complex, the harder the fineλ 太小 → 乱线背题(过拟合);太大 → 平板不敢学(欠拟合);中间最好λ too small → wild memorising line (overfitting); too big → flat plank (underfitting); the middle is best常见实现叫“权重衰减”(weight decay):训练分略降一点,测试误差明显更低——值A common form is weight decay: training scores dip slightly, test loss drops clearly — worth it
内容参考 OpenStax 等公开教材,多来源核对 · AI 生成、人工审核 · 发现错误欢迎指正,帮这片叶子长得更好。Based on OpenStax and other open textbooks, cross-checked across sources · AI-generated, human-reviewed · Spotted a mistake? Tell us — help this leaf grow.
 Back to tree